Glossary · AI Engineering · 5-min read
AI-Native Application Architecture
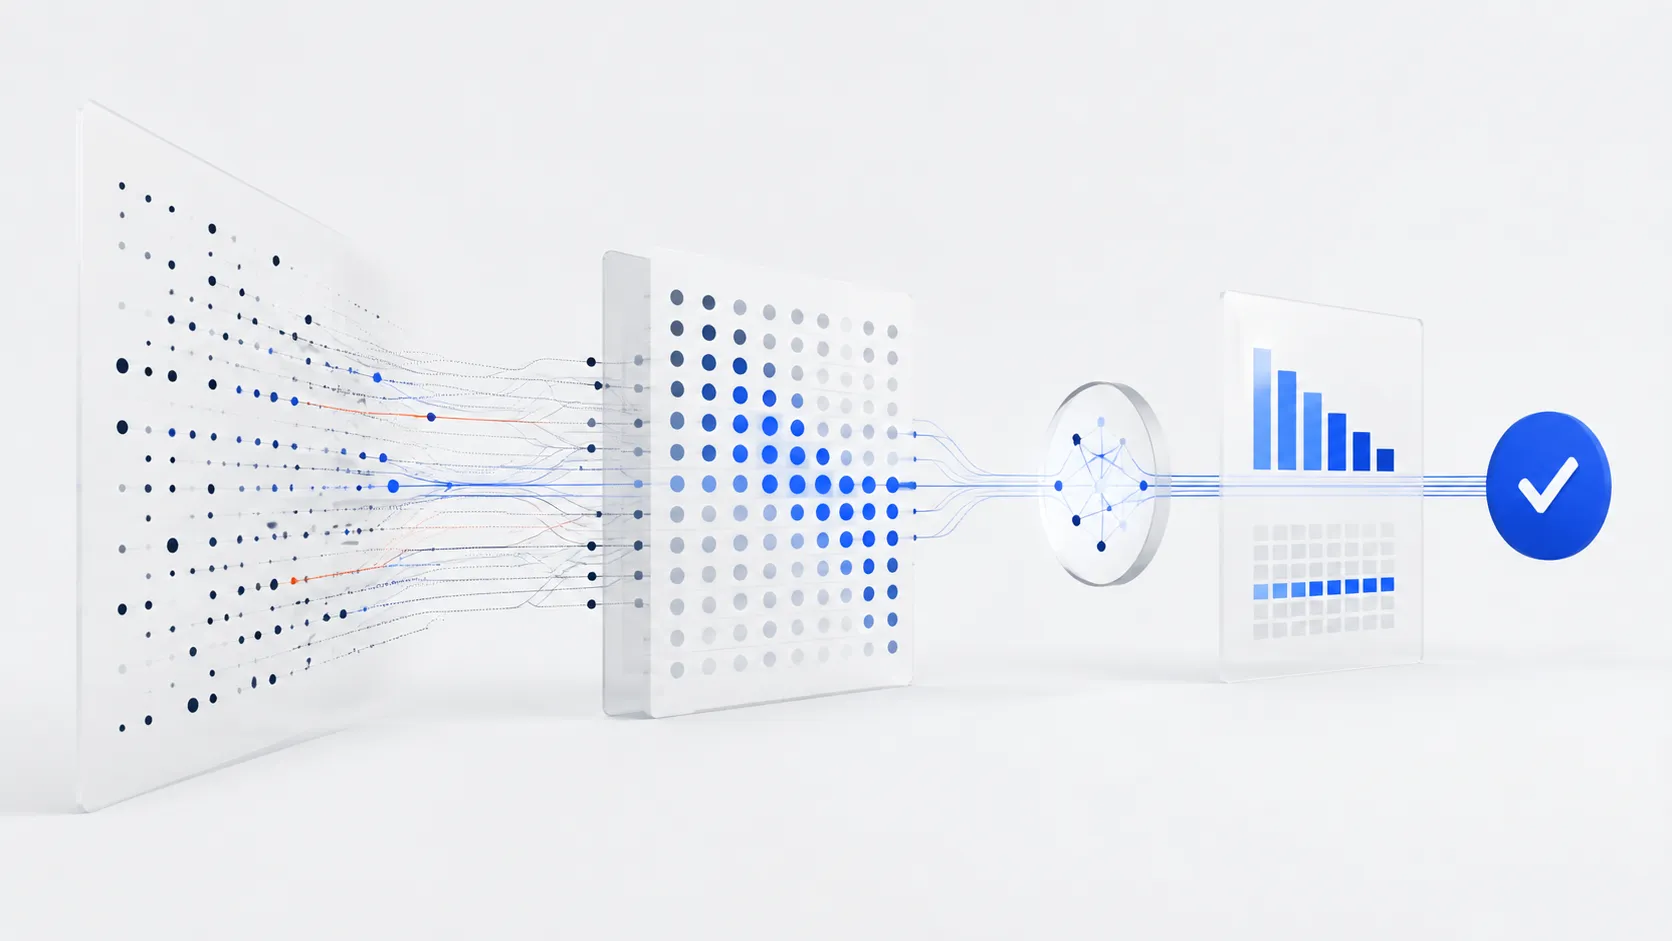
Definition: An AI-native application is software designed from inception around autonomous agent workflows and large language models rather than traditional static CRUD databases. It incorporates vector search (such as pgvector or Qdrant), structured JSON function calling, context retrieval pipelines, and automated fallback logic to deliver deterministic business outcomes at sub-second response latencies.
Adding a chat widget to the corner of a legacy web app does not make it AI-native. In an AI-native architecture, the language model acts as a deterministic reasoning and routing engine inside the core transaction loop -- extracting structured entities from unstructured PDFs, executing SQL/API tools under strict permission bounds, and verifying outputs before writing to the database.

System Layer | Production Stack Standard | Engineering Guardrail |
|---|---|---|
Context & Memory | PostgreSQL + | Strict tenant isolation so Organization A can never retrieve Organization B's embeddings |
Structured Execution | FastAPI + Pydantic / TypeScript Zod tool schemas | 100% typed JSON outputs; rejects malformed model responses before hitting database APIs |
Latency & Routing | Server-Sent Events (SSE) + Semantic Redis Cache | Sub-400ms time-to-first-token; routes simple classification to fast models and complex logic to frontier models |
Verification & Evals | 100+ golden test cases run in GitHub Actions CI | Automated regression gate blocks deployment if accuracy drops or hallucination rate exceeds 0% |
At Horizon Labs, we scope AI-native MVPs around one measurable workflow automation -- such as automated compliance auditing, multi-source procurement matching, or autonomous GTM pipeline enrichment -- shipping production code on a fixed-price milestone schedule.
An AI wrapper passes raw user text to a single LLM endpoint with no state control or verification. An AI-native application enforces tenant-isolated vector retrieval (RAG), Pydantic/Zod JSON schema validation, deterministic tool calling, and automated CI/CD evaluation suites.
The proven production stack combines Next.js 15 (TypeScript) for streaming UI, Python (FastAPI) for orchestration, PostgreSQL with pgvector and Row-Level Security (RLS) for unified relational and vector storage, and multi-provider routing across OpenAI, Anthropic, and Gemini.
Tour live marketplaces, YC-backed MVPs, and architecture teardowns built by our senior team.
View Client Case Studies →See fixed-price sprint breakdowns, weekly milestone rates, and our 6-month code warranty.
Explore Pricing & Scopes →Direct 15-minute scoping call with Saif Akhtar (Head of Product & Engineering). No sales reps.
Book 15-Min Scoping Call →An AI wrapper passes raw user text to a single LLM endpoint with no state control or verification. An AI-native application enforces tenant-isolated vector retrieval (RAG), Pydantic/Zod JSON schema validation, deterministic tool calling, and automated CI/CD evaluation suites.
The proven production stack combines Next.js 15 (TypeScript) for streaming UI, Python (FastAPI) for orchestration, PostgreSQL with pgvector and Row-Level Security (RLS) for unified relational and vector storage, and multi-provider routing across OpenAI, Anthropic, and Gemini.
Tell us what you're building. After an intro call with our founders, you'll hear back within 72 business hours: a written scope with an hour range and a hard ceiling, or the questions we need answered first.